 POC
AI Model Fine-Tuning & SLMs
Evaluate the right model for your task and test whether adaptation improves the results. GenAI Protos provides LLM fine-tuning services, open-model evaluation, and small language model assessments for focused business use cases.
How We Help
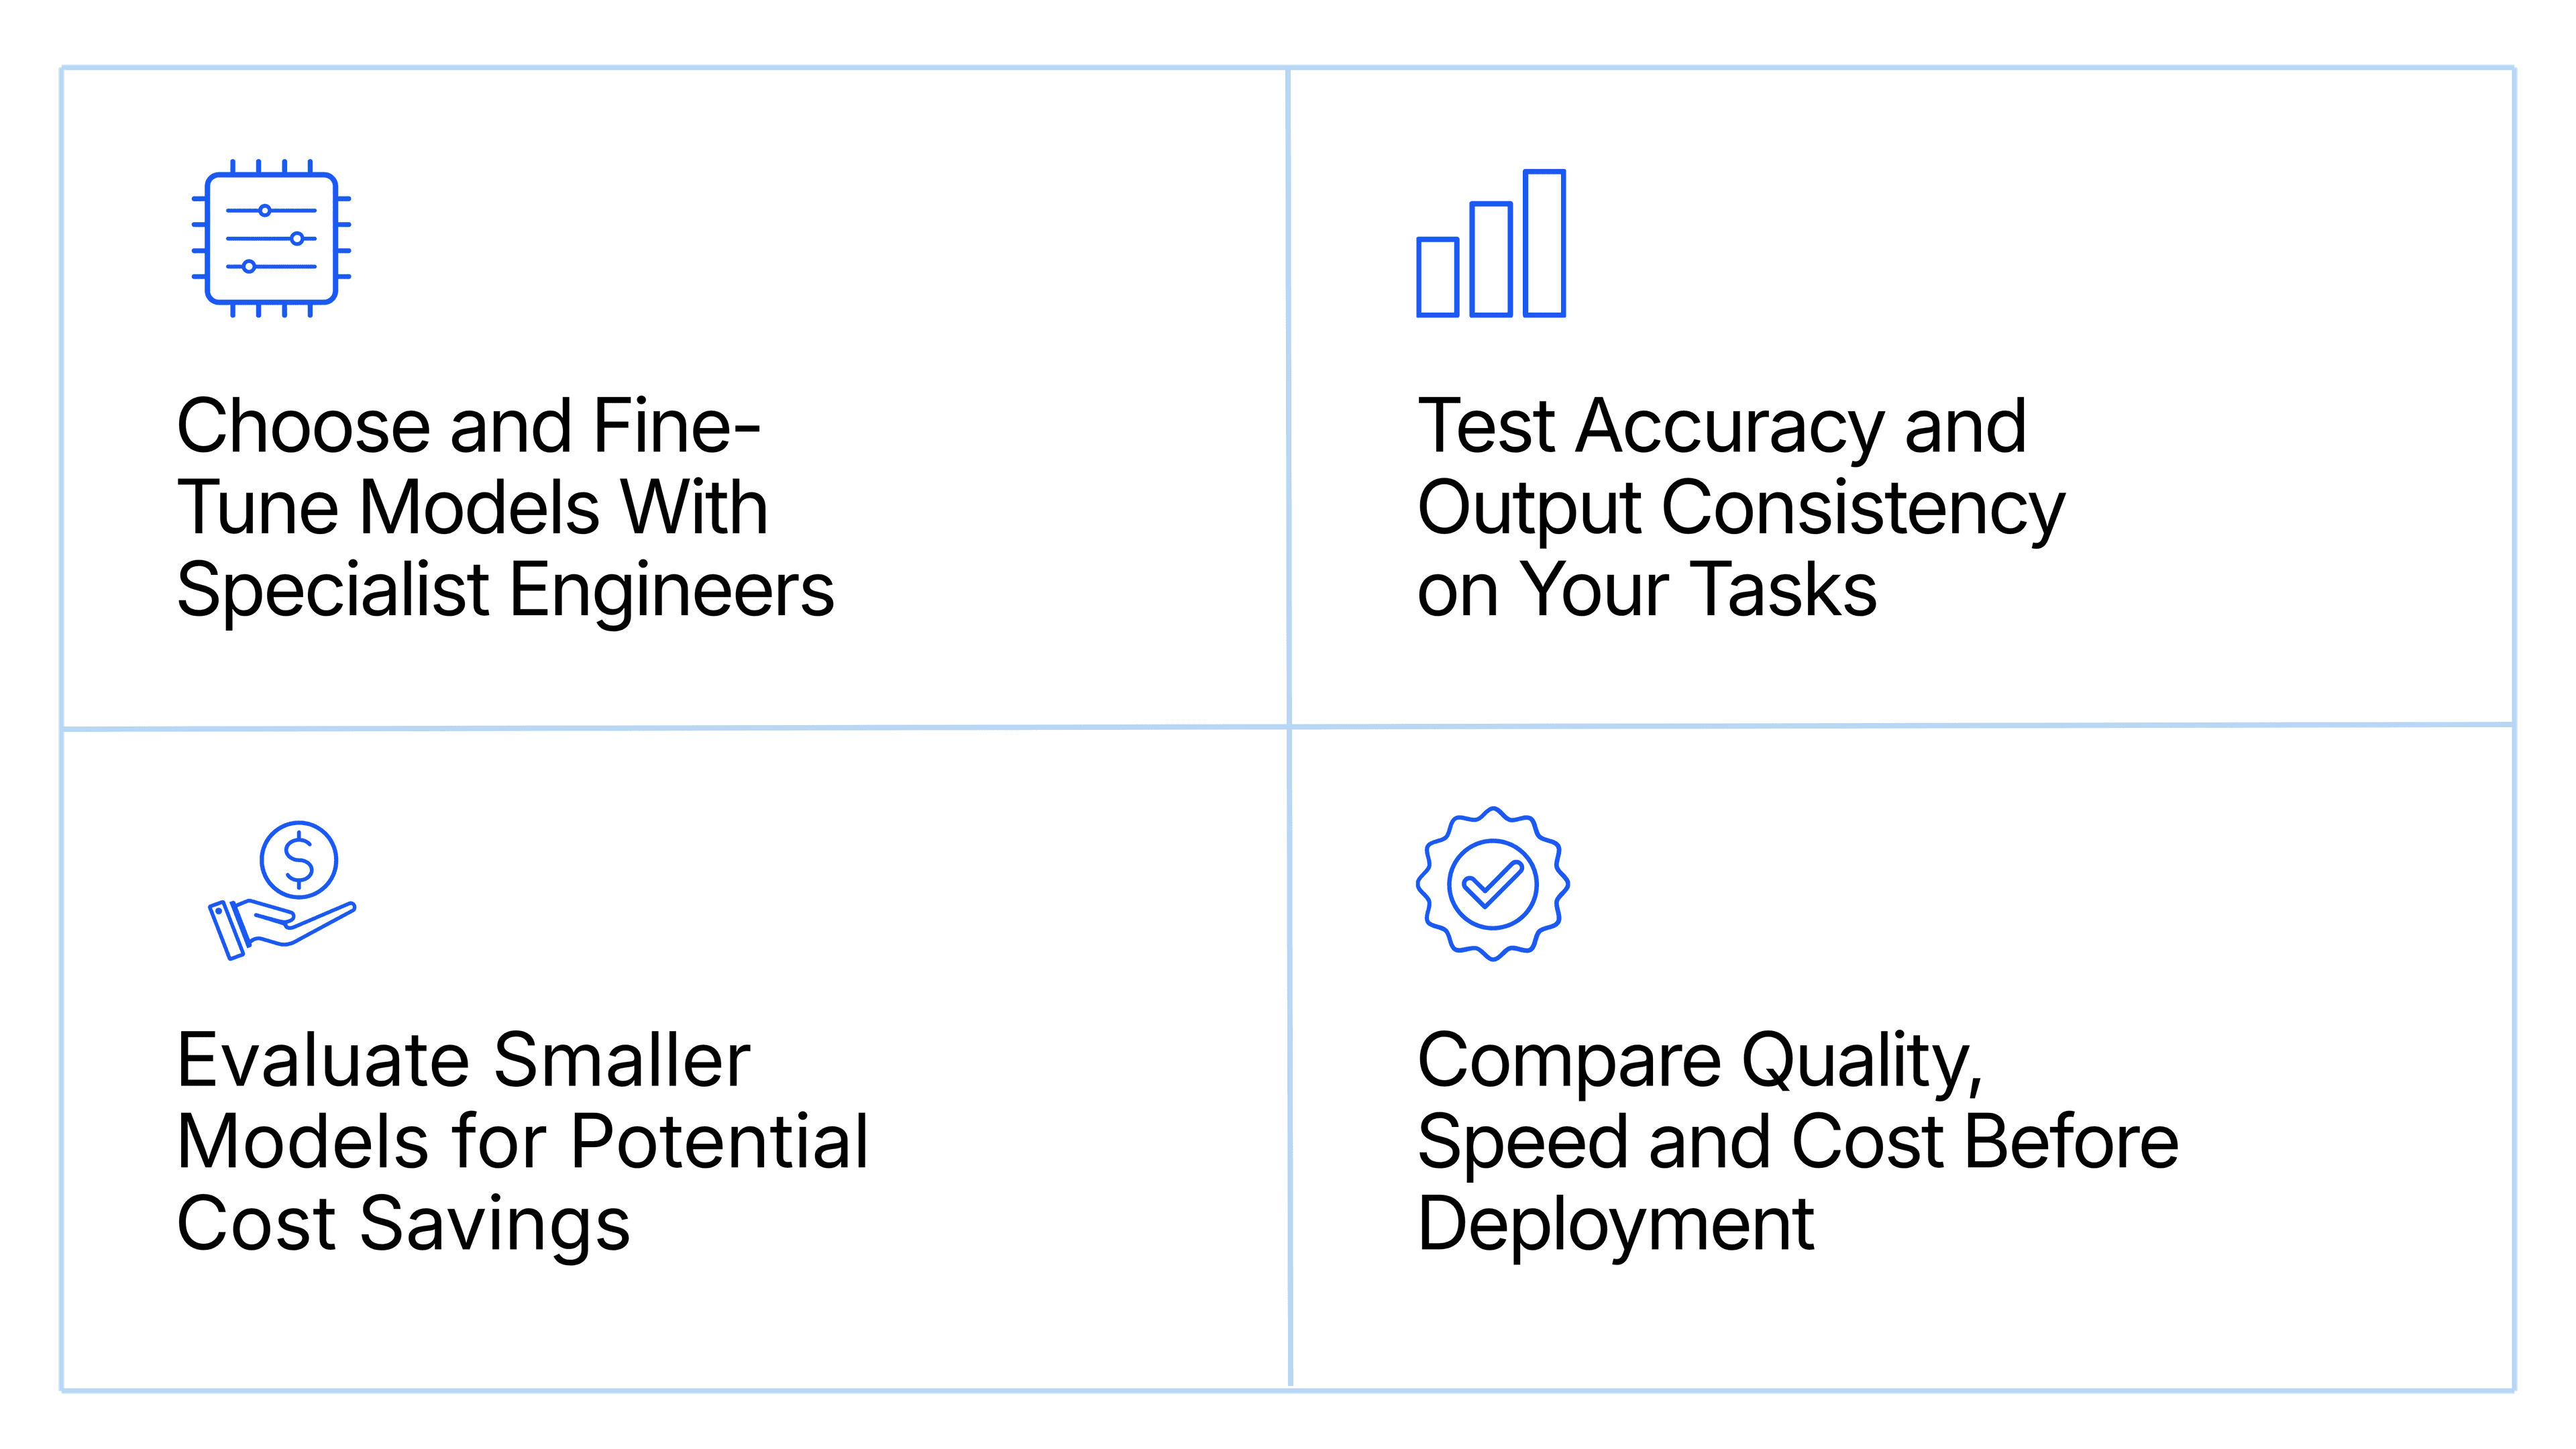
Our AI model fine-tuning and small language model services help you explore open models, adapt model behavior, and evaluate performance on focused tasks.
Explore Open-Source Models
Evaluate open-source and open-weight models against your quality, resource, and licence requirements before considering open-weight model fine-tuning or other adaptation.
Fine-Tune AI Models
Use custom LLM fine-tuning to adapt a selected language model with workflow examples and measure changes against its baseline performance.
Explore Small Language Models
Use small language model evaluation to test focused tasks such as classification, information extraction, or structured response generation.
Prepare Training and Evaluation Data
Get support with LLM training data preparation and separate evaluation datasets for meaningful training and performance comparisons.
Improve Output Consistency
Test approaches to improve required formats, terminology, tone, and task behavior using agreed evaluation criteria.
Compare Quality, Speed, and Cost
Benchmark base and adapted models to understand performance tradeoffs and estimated operating costs before deployment.
Benefits of Working With Us
Identify Suitable Models Faster
Narrow your options through task-specific evaluations before spending time adapting an unsuitable model.
Access Model Engineering Expertise
Get support with model selection, training data, fine-tuning, and evaluation without building a specialist team first.
Test Opportunities to Reduce Cost
Evaluate whether smaller or adapted models can meet your quality needs at a lower total operating cost.
Measure Quality on Your Tasks
Compare accuracy, output consistency, and failure cases using separate evaluation data before deciding on deployment.
What You Get
Open-Model Evaluation
Evaluate selected open-source and open-weight models against your tasks, data, and environment. Review task performance, resource requirements, licence conditions, and deployment dependencies before choosing a candidate.
Deliverables:
- A model shortlist aligned with your requirements.
- Working evaluation setup and test cases.
- Quality, response-time, and resource comparisons.
- Selection findings and recommended next steps.
LLM Fine-Tuning
Domain-specific LLM fine-tuning adapts a pretrained model using examples from your business tasks. We prepare the agreed data, adapt a selected model, and compare it with the baseline using separate evaluation data. Before recommending training, we assess whether model selection, improved prompting, or retrieval could address the requirement.
Deliverables:
- Prepared training and separate evaluation datasets.
- Fine-tuned model or adapter where supported and agreed.
- Before-and-after task-performance report.
- Training configurations and documentation.
- Known limitations and handover assets.
Small Language Model Exploration
Test whether a smaller language model can perform a focused task, such as classification, information extraction, or structured response generation. Explore small language model fine-tuning where needed and compare results with an appropriate baseline. The evaluation establishes whether the model meets your quality requirements and offers useful tradeoffs in response time, infrastructure, or estimated operating cost.
Deliverables:
- SLM shortlist and task-specific evaluation.
- Adaptation experiment where required.
- Working inference setup.
- Quality, latency, and estimated cost comparisons.
- Deployment recommendations and next steps.
Cost and timelines
LLM fine-tuning cost depends on model selection, training-data preparation, evaluation scope, compute, and the required inference setup. We agree on the scope, price, and milestones before starting.
Compute, hosting, model usage, and any licensing costs are identified separately where applicable. Handover arrangements depend on the platform, model licence, and engagement agreement.
Relevant work
POCCommon Questions About Fine-Tuning and Small Language Models
We help you test whether fine-tuning improves performance on your specific tasks, terminology, and output requirements. We compare the adapted model with its baseline using separate evaluation data to measure improvements and remaining failure cases.
We benchmark selected small language models using your tasks and representative data. The assessment compares output quality, response time, resource requirements, and estimated operating costs to establish whether a smaller model is suitable.
Yes, our engineers assess selected models against your task requirements, deployment environment, available resources, and licence conditions. You receive a practical comparison that helps you narrow the options before investing in adaptation or deployment.
Yes, we review your available examples, identify gaps, and help organize task-specific training and separate evaluation datasets. We also assess whether the data is sufficient for a meaningful fine-tuning experiment before recommending training.
Yes, our LLM fine-tuning consulting can begin with an assessment of baseline performance, data, quality requirements, and deployment constraints. The findings help you decide whether fine-tuning warrants further investment and what that engagement would require.
Related services
Explore adjacent AI capabilities tailored to solve your technical and operational challenges.
What would you like your model to do?
Share the task, available data, current model, and where the outputs fall short. We will help define the right evaluation and a practical next step.
Let's Explore Your Idea
Tell us what you want to build, test, or improve. You don't need a detailed brief to get started.